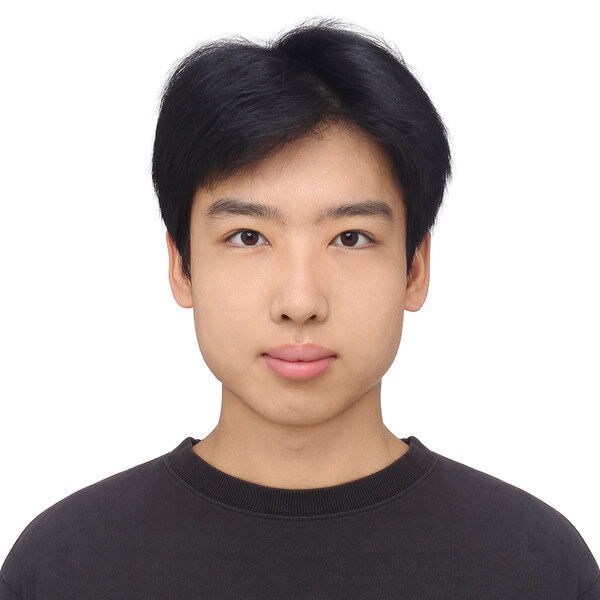
I am an undergraduate in Computer Science at the University of Michigan, Ann Arbor. Previously I studied Electrical and Computer Engineering at Shanghai Jiao Tong University.
I am interested in building embodied agents that interact with the physical world — in particular, how reinforcement learning, foundation models, and world models can be combined to build generalist robots. Currently, I am an undergraduate researcher in the ARM Lab at Michigan, advised by Prof. Dmitry Berenson. I also work with Prof. Yao Mu's group at ScaleLab (SJTU) on RL fine-tuning for vision-language-action policies.
News
- Sep 2026Joined the ARM Lab at the University of Michigan as an undergraduate researcher, advised by Prof. Dmitry Berenson.
- Aug 2026Joined the University of Michigan, Ann Arbor as a B.S.E. student in Computer Science.
- Jun 2026Preprint of Q-VGM, our off-policy RL fine-tuning method for flow-matching VLA policies, is on arXiv.
- May 2026Started as a research intern at AgiBot, Shanghai.
- Scene2Gym is accepted at IROS 2026.
- Oct 2025Joined ScaleLab @ SJTU as a research intern, advised by Prof. Yao Mu.
Publications

An offline-to-online RL method for fine-tuning flow-matching VLA policies with a learned critic. Applying critic gradients to a flow policy normally means backpropagating through the multi-step denoising process, which is costly and unstable at VLA scale. Motivated by an optimal-control view of denoising, Q-VGM turns clean-action value gradients into local velocity corrections at late denoising steps and fine-tunes the pretrained action expert by matching these critic-guided targets, with gradients flowing only through local velocity predictions. On LIBERO it lifts a few-shot-SFT π0.5 policy from 84.6% to 90.7% offline and to 98.4% after online training, with 5.3× the sample efficiency of on-policy RL; on three real-world bimanual tasks, offline Q-VGM raises average success from 66.7% to 98.3%.

A framework that turns real-world scene observations into interactive, metric-consistent digital twins for embodied policy learning. It combines 3D Gaussian Splatting for photorealistic rendering with an object-centric metric-alignment pipeline that anchors reconstructed assets to real-world scale, and a hybrid co-simulation stack that decouples rendering from the physics clock for closed-loop training. Imitation-learning policies trained purely on Scene2Gym-synthesized data match policies trained on real human demonstrations, articulated-object manipulation transfers zero-shot to a real microwave-heating task, and visual RL policies reach a 56% zero-shot real-world success rate.
Research Experience
Advisor: Prof. Dmitry Berenson
Reinforcement learning for robotics and post-training of vision-language-action (VLA) policies.
Built an end-to-end SFT and RL post-training framework for flow-matching VLA policies (π0.5), integrating real-robot deployment, rollout data collection and processing, and distributed training into a closed loop. Implemented and benchmarked RL post-training algorithms including DS-RL, RLT, and Q-VGM, raising real-robot success from 75% to 95% on cloth folding (deformable, long-horizon) and from 33% to 79% on phone-charger plug insertion (high-precision, contact-rich).
Advisor: Prof. Yao Mu
First-author work on Q-VGM, an offline-to-online RL fine-tuning method for π0.5 (a 3B-parameter flow-matching VLA policy): on LIBERO it lifts a few-shot-SFT policy from 84.6% to 90.7% offline and 98.4% online with 5.3× the sample efficiency of PPO, and raises average success on three real-world bimanual tasks from 66.7% to 98.3%.
Advisor: Prof. Qin Tong
Co-developed Scene2Gym (IROS 2026), converting real-world scenes into interactive 3DGS digital twins; led the RL and imitation-learning training pipeline, achieving 56% zero-shot sim-to-real transfer for visual RL policies.
Education
B.S.E. in Computer Science
B.E. in Electrical and Computer Engineering · GPA 3.95/4.0
Technical Skills
Programming: Python, C++ (NOIP First Prize), MATLAB
Frameworks: PyTorch, MuJoCo, Isaac Gym, ROS, Weights & Biases, Claude Code